Sam Zimmermann · 18 September 2026
Leveraging Machine Learning for Anomaly Detection in Organic Traffic Streams
Organic traffic streams consist of visitors arriving through unpaid search results and referrals rather than paid advertisements, and these flows carry measurable patterns in volume, timing, and user behavior that shift under various conditions. Researchers apply machine learning models to scan these streams continuously because manual review cannot keep pace with the volume of requests recorded by analytics platforms each day. Data from server logs and tools such as Google Analytics provide the raw inputs that algorithms process to flag deviations from established baselines.
Defining Anomalies in Organic Traffic
Anomalies appear as sudden spikes, prolonged drops, or irregular distributions in session duration and page depth that deviate from historical norms for a given site. Seasonal events, search engine algorithm updates, and indexing changes produce predictable shifts, whereas bot infiltration or technical errors generate less expected disruptions. Observers note that distinguishing these categories requires models trained on labeled examples of both normal and irregular periods so that classification accuracy improves over successive iterations.
Machine Learning Approaches Applied to Traffic Data
Unsupervised techniques such as isolation forests and density-based clustering identify outliers without prior examples of anomalies, which proves useful when labeled datasets remain scarce. Supervised methods rely on historical records of confirmed incidents to train classifiers that assign probability scores to new observations. Autoencoders learn compressed representations of normal traffic and reconstruct inputs with higher error rates when anomalies occur, offering a reconstruction-based detection signal. Hybrid pipelines combine these methods so that initial filtering by unsupervised models reduces the volume passed to more computationally intensive supervised stages.
Data Preparation and Feature Engineering
Raw logs undergo cleaning to remove internal traffic, test bots, and incomplete sessions before feature extraction begins. Engineers derive metrics including request rate per minute, geographic distribution of IP addresses, referrer diversity, and time-between-visits distributions that capture behavioral nuances. Time-series decomposition separates trend, seasonal, and residual components so that models focus on residuals where anomalies concentrate. In September 2026, updates to several major analytics platforms introduced additional fields for device fingerprinting that enriched feature sets used in production pipelines.
Model Training and Validation Practices
Teams partition datasets chronologically to preserve temporal order and prevent leakage from future data into training sets. Cross-validation across multiple sites verifies that models generalize beyond a single domain’s traffic profile. Precision-recall curves guide threshold selection because false positives consume analyst time while missed anomalies allow problems to compound. Continuous retraining schedules incorporate recent traffic windows so that models adapt to gradual shifts in user behavior and search engine indexing patterns.
Integration with Monitoring Systems
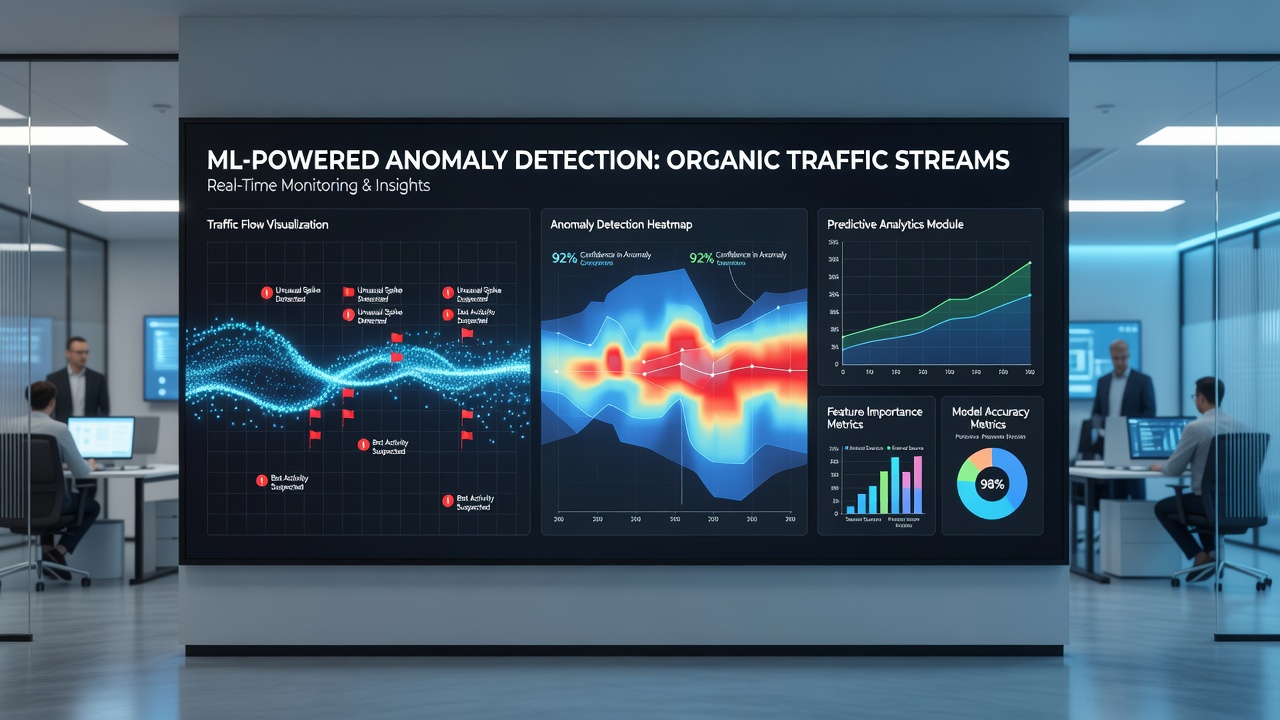
Detected anomalies trigger alerts through existing notification channels so that site operators receive notifications within minutes of threshold breaches. Dashboards display both raw metric values and model confidence scores, allowing quick triage before deeper investigation. Automated remediation scripts sometimes pause certain tracking tags or adjust crawl directives when anomalies correlate with known crawler misbehavior patterns. These workflows reduce mean time to response compared with manual log inspection alone.
Documented Applications Across Industries
E-commerce platforms have recorded instances where models identified indexing errors after site migrations that would otherwise have remained undetected for weeks. News outlets apply similar systems to separate genuine reader surges from coordinated referral spam campaigns. Academic studies published through IEEE conferences detail how university research sites used clustering to surface crawler activity that distorted download statistics for open datasets. Each case demonstrates that the same core techniques transfer across domains when features are adapted to the specific traffic characteristics of the site.
Challenges and Limitations Observed in Practice
Concept drift occurs when user behavior evolves faster than retraining cycles, causing previously reliable baselines to lose relevance. Privacy regulations limit the granularity of IP and device data that can be retained, which reduces feature richness available to models. Adversarial actors may attempt to mimic normal patterns to evade detection, requiring ongoing evaluation of model robustness. Resource constraints at smaller organizations sometimes limit access to the compute needed for frequent model updates, leading to reliance on simpler rule-based thresholds supplemented by periodic manual review.
Conclusion
Machine learning systems process organic traffic streams by learning normal patterns and surfacing deviations that warrant attention. Implementation involves data preparation, feature engineering, model selection, and integration with alerting infrastructure. Organizations that maintain these pipelines gain earlier visibility into indexing issues, bot activity, and behavioral shifts. Continued refinement of training data and adaptation to new platform features sustain detection performance as traffic characteristics evolve.